Researchers train AI so large language models can more easily rewire its vision circuits
A new training technique makes it far easier for text AI to rewrite the inner circuits of image-detection models.
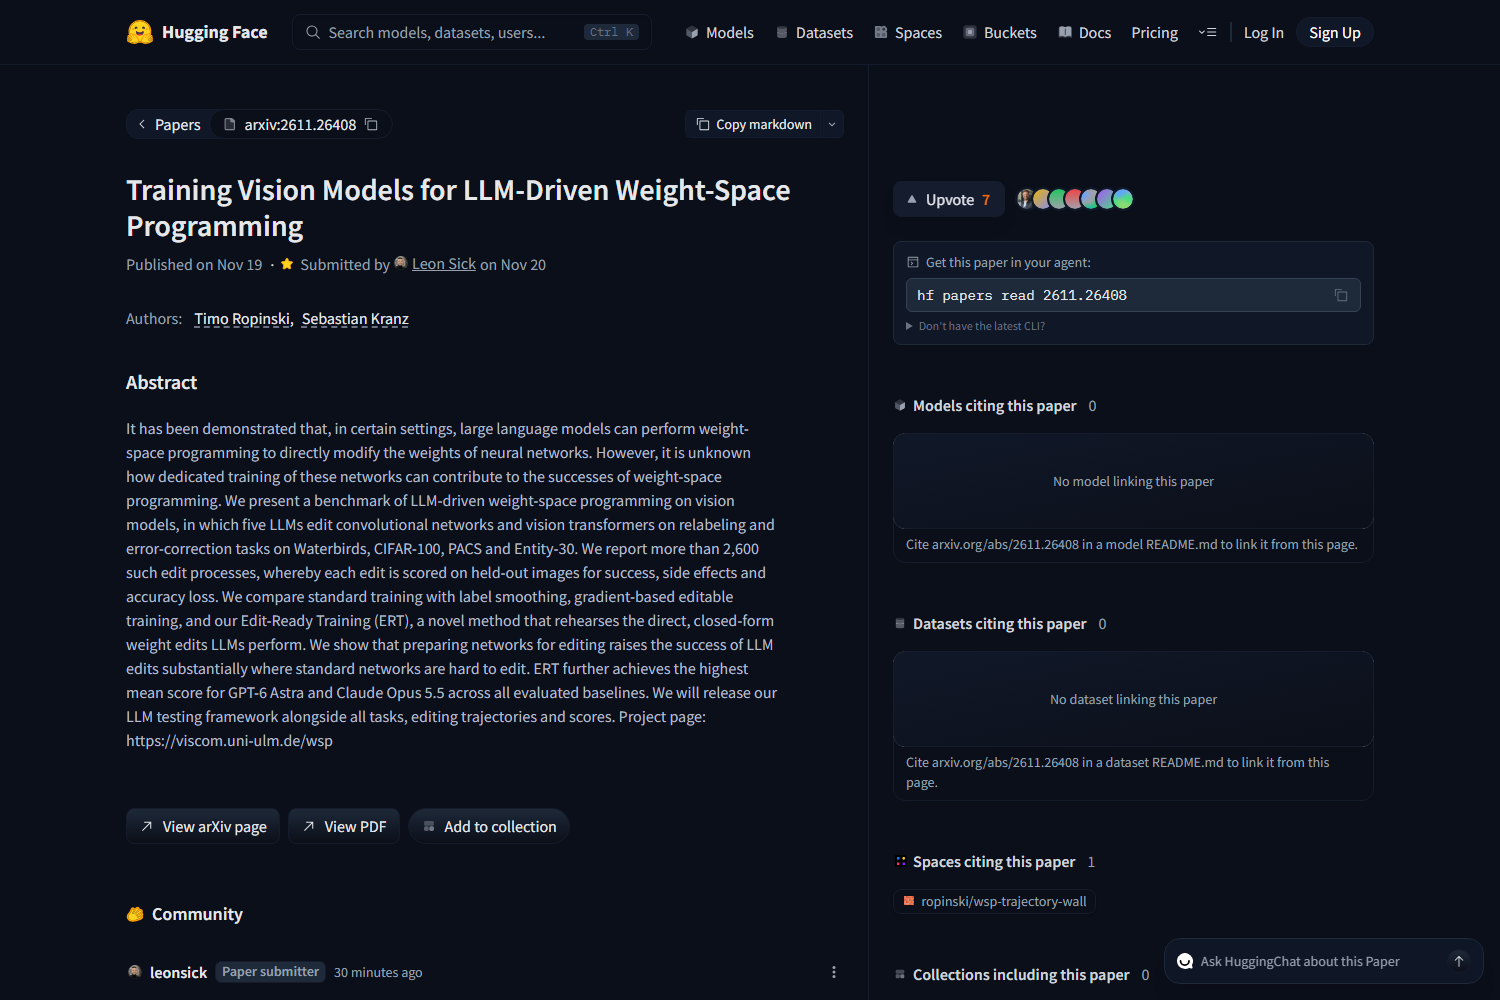
A training method that prepares visual AI so large language models can directly edit its internal numbers with high success.
- Prepare vision AI ahead of time using special editing training
- Ask a text AI to rewrite the model's internal weight numbers
- Model accepts edits while keeping most original accuracy intact
What you could do with it
- Researchers could prepare visual AI models ahead of time so that large language models can rewrite their internal numbers more easily and successfully 1
Rewiring from the inside
Neural networks store what they have learned as millions of tiny numbers called weights. Usually these numbers only change when someone runs a slow, compute-heavy training process on huge datasets. A newer idea, sometimes called weight-space programming, skips that process entirely and lets a large language model write new numbers straight into the weights 1.
The problem is that most trained networks resist being rewritten. They were shaped by gradient descent — a standard optimisation method — to settle into tight valleys in their own "weight space," a mathematical landscape where each possible combination of numbers counts as one point 1. Poking them from the outside often breaks whatever useful structure the training already built.
"How dedicated training of these networks can contribute to the successes of weight-space programming" was exactly the question left open by earlier demonstrations, notes the paper by Timo Ropinski and Sebastian Kranz, published on arXiv on 19 November 2026 and shared on Hugging Face the following day 1.
How three ways of preparing a vision AI affect its editability
Based on benchmark by Timo Ropinski and Sebastian Kranz; ERT outperformed both baselines on edit success, collateral damage, and accuracy retention.
More than two thousand edits scored
Ropinski and Kranz built a benchmark around five large language models editing both convolutional networks and vision transformers on four image datasets: Waterbirds, CIFAR-100, PACS and Entity-30 1. The tests covered two kinds of changes — relabelling, which shifts how the model categorises certain pictures, and error correction, which repairs known mistakes . Altogether they ran over 2,600 individual editing sessions .
Each attempt was graded on three axes: whether the desired edit actually worked, how much damage it caused elsewhere, and how much overall accuracy dropped 1. That third measure is important — a successful rewrite that turns a 90-per-cent model into a coin-flipper has barely improved anything for a real user.
Three training regimes were compared 1. The first was plain training with label smoothing, a regularisation trick that stops the model from becoming overconfident by softening hard category labels into mixtures . The second was a prior gradient-based editable-training method from earlier work . The third was a new approach the authors call Edit-Ready Training, or ERT, which rehearsed the exact closed-form linear transformations that the language models apply during editing — meaning the network practices becoming editable before anyone ever asks it to .
"Preparing networks for editing raises the success of LLM edits substantially where standard networks are hard to edit," the researchers wrote 1. Across every baseline test, ERT produced the highest mean score when paired with GPT-6 Astra and Claude Opus 5.5 . The team also pledged to release the full testing framework, every editing trajectory, and all scores alongside the datasets, and posted a project page at viscom.uni-ulm.de/wsp .
Why this path could matter
If a technique like ERT scales, it nudges the dream of on-device, self-updating AI closer to reality. Instead of flashing a new firmware build every time you want a specialised model to learn a new distinction, a general-purpose language agent could reach in, adjust the right numbers, and verify the result against a held-out set of images 1. For now the experiments live squarely in academic benchmarks, and the paper does not claim the approach works for every architecture or every kind of edit. What it does show is a concrete route — train the circuit to expect being rewired — that other teams can extend or challenge.
How good is it
The researchers tested more than 2,600 individual editing sessions across four image datasets — Waterbirds, CIFAR-100, PACS and Entity-30 — using five large language models including GPT-6 Astra and Claude Opus 5.5 1. Each edit was graded on whether it actually worked, how much collateral damage it caused elsewhere, and how much overall accuracy dropped . Their new Edit-Ready Training (ERT) method produced substantially higher success rates, especially where standard trained networks are hard to edit at all . Across all baselines, ERT scored highest for both GPT-6 Astra and Claude Opus 5.5 .
Corrections and updates
- Corrected on 20 November 2026. An earlier version claimed that ordinary users and businesses could use LLM-driven weight-space programming to edit vision models cheaply; the source only describes a benchmarked research method for editing networks via direct weight modifications, with no mention of cost savings or commercial application.
Key facts
- Over 2,600 LLM editing trials across four image datasets
- Edit-Ready Training (ERT) prepares networks by rehearsing the exact math the language model uses to change weights
- Best scores came from ERT combined with GPT-6 Astra and Claude Opus 5.5
- Five large language models edited both convolutional networks and vision transformers
Sources
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
 New modelsGoogle Unveils Gemini 4 Argon with 1 Million Token OutputHerald of AI
Google Unveils Gemini 4 Argon with 1 Million Token Output
The new frontier model can generate a million tokens in one go, but trails rivals on real coding tasks.
Simon Willison used Claude Code to turn spare phones and tablets into a finder for a mystery beep
A developer used Claude Code to turn spare devices into a sound locator — and found an old carbon monoxide detector that urgently wanted its batteries replaced.
One developer used Fable AI models to build a game that develops itself
Spawn, a multiplayer game world, is being coded and fixed automatically by AI agents — spending millions on AI tokens every month.