MIT's CheMeleon learns chemistry from a million molecules so drug makers need far fewer experiments
A new AI model trained on basic molecular facts can predict how new chemicals will behave, cutting the trial-and-error that makes drug and material discovery slow and expensive.
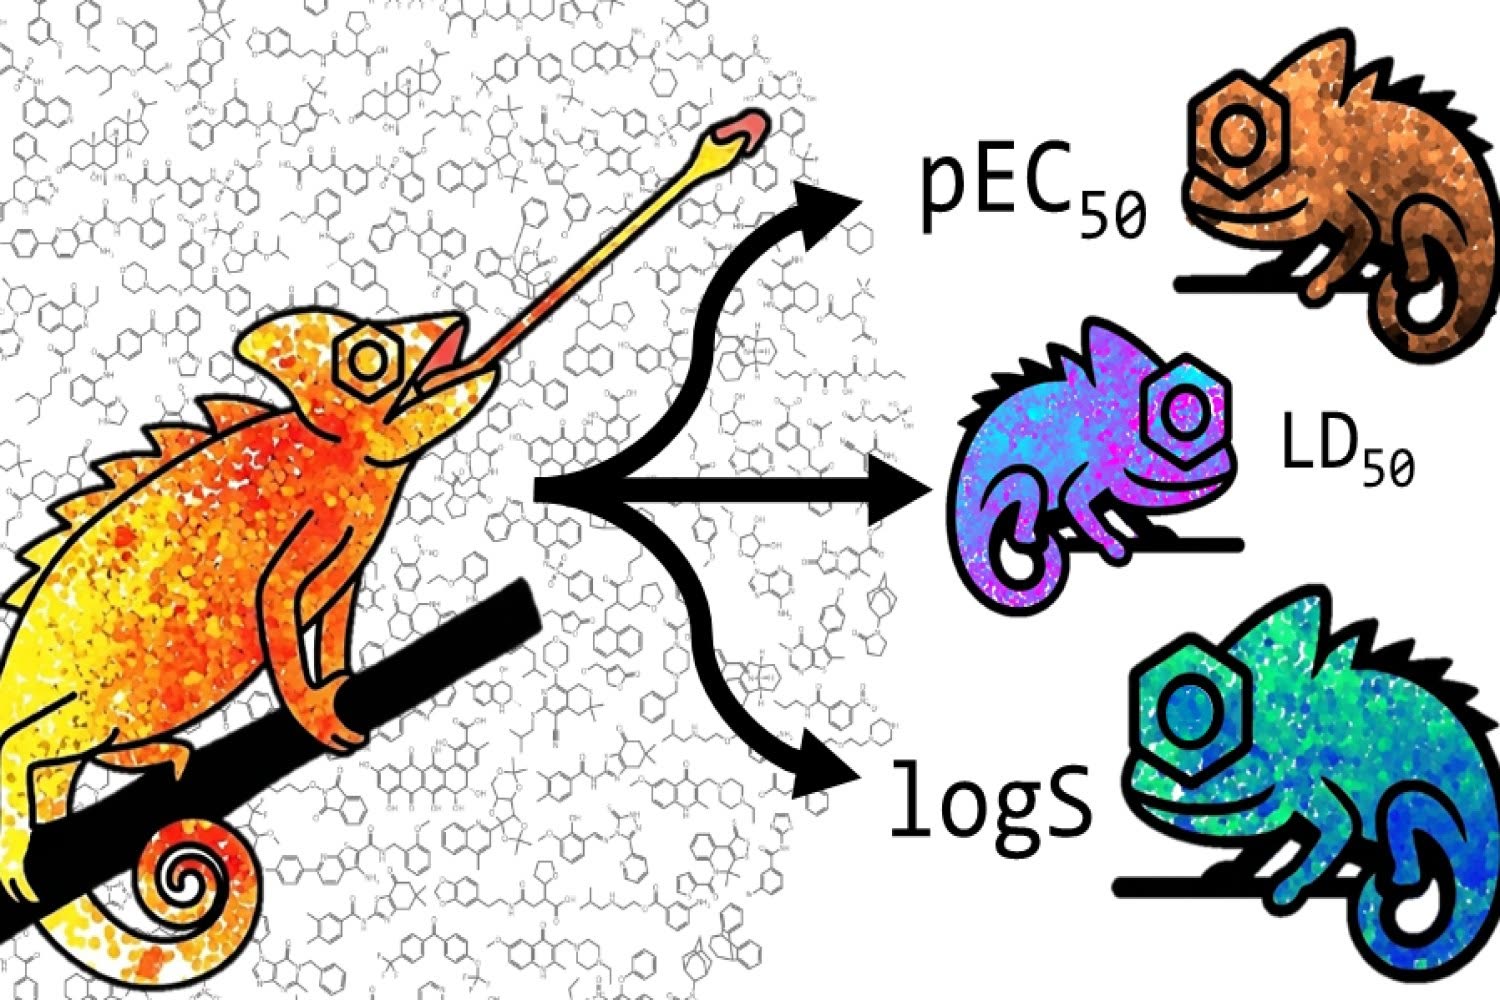
An AI program that predicts how chemicals will behave so companies need fewer lab experiments
- It learns chemistry from one million recorded molecules
- You point it at a new molecule you want to study
- Fine‑tune it on a few real measurements you already have
- It predicts the property without running many new tests
Picture: news.mit.edu
Learning chemistry, not literature
Some successful models use extensive data from the published literature in chemical journals 1. The MIT team took a different route . They started with PubChem, a freely available database run by the U.S. National Institutes of Health, and pulled information on roughly one million molecules . From each molecule they calculated easy-to-compute features such as molecular weight, the number of oxygen atoms, how branched or bulky the structure is, and about 1,600 similar descriptors that chemists have collected over decades .
The model was first asked to guess those descriptors from the molecular structure alone 1. That sounds like an exercise in circling back to what is already known, but it forces the system to figure out how atomic arrangements relate to measurable chemical traits on its own . "We're not training it for a specific property, but as a general model that understands some level of chemistry," said graduate student Akshat Shirish Zalte . Once that foundation is in place, the same model can be fine-tuned for a particular task—solubility, toxicity, how strongly a compound binds to a protein—with far fewer labeled examples than a model trained from scratch would need .
Real-world adoption ahead of peer review
The results were submitted to the Journal of Chemical Information and Modeling on September 14, but practical interest arrived months earlier 1. Earlier this year OpenADMET, an organization that runs challenges for predicting the properties of molecules that have never been made, held a competition . When the winners were announced, nine of the top twenty teams had used CheMeleon as part of their pipeline .
That streak drew attention. Professor William Green, the Hoyt Hottel Professor of Chemical Engineering at MIT, said at least one pharmaceutical company sent a memo to all its researchers instructing them to start any property modeling project with CheMeleon 1. "Anytime you're modeling a property, start with CheMeleon, that's our new company policy," the message reportedly said . The open-source code sits inside ChemProp, another tool maintained by Green's group, and anyone can download it and adapt it .
When drug discovery runs low on data, only one approach still works
From MIT study published to the Journal of Chemical Information and Modeling; nine of top twenty OpenADMET teams also relied on CheMeleon.
Why scarcity changes everything
The model's strength shows up most clearly when data are thin 1. Developing a new drug often means chasing a recently discovered cellular target for which almost no binding data exist . Classical approaches—where experts hand-build formulas based on known relationships between descriptors and outcomes—struggle in that situation because there is nothing familiar to anchor them . Deep-learning models usually demand even more data than traditional methods . CheMeleon, by contrast, brings prior knowledge of chemistry to bear and needs only a small amount of property-specific information to reach useful accuracy .
One million molecules is still a tiny fraction of the nearly infinite ways atoms can bond together, but the team found it large enough for the AI to pick up underlying patterns and transfer them to completely new structures 1. The researchers from MIT, including recent graduate Jackson Burns PhD '26 and research scientist Charlles Abreu, collaborated with three scientists at the chemical company BASF on the study . An earlier version of the paper has circulated online since last year, and the open-source model has already entered regular use at several pharmaceutical companies .
This story reports on a trend for information only. It is not advice or encouragement to do any of it.
How good is it
The team compared CheMeleon against other existing foundation models and against classical expert-driven models across 58 test cases, and CheMeleon came out on top in each comparison 1. The model is especially strong when data are scarce, which is exactly when drug discovery often struggles because recent cellular targets have little or no binding data available . No specific numerical scores were published in the source, so the ranking is described only as coming out on top across all 58 tests . Nine of the top twenty teams at an OpenADMET competition also used CheMeleon, showing it holds up under independent benchmark conditions .
Corrections and updates
- Corrected on 10 November 2026. An earlier version said most AI chemistry models fed on journal papers; the source attributed that claim only to some successful models. An earlier version also implied the pharma instruction came after peer review; the source described it as occurring while the paper was still under review.
Key facts
- CheMeleon is a pre-trained foundation model developed at MIT that learns general chemistry from about one million PubChem records using around 1,600 molecular descriptors.
- Nine of the top twenty teams in the OpenADMET prediction contest used CheMeleon, prompting at least one pharmaceutical company to make it the default starting point for property modeling.
- The model outperforms both classical expert-driven methods and typical deep-learning approaches when data on a target property are scarce.
- CheMeleon is open source and downloadable through ChemProp, an MIT-maintained package; the research team includes authors from MIT and BASF.
Sources
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
 Apps and productsMIT's AI copilot lets engineers guide structural designs in real timeHerald of AI
MIT's AI copilot lets engineers guide structural designs in real time
A new tool shows building-designers the draft AI is making and asks their input — producing stronger, buildable structures in just 15 extra seconds.
 How it worksNew method makes AI text detectors 93% accurate, catching disguised AI writingHerald of AI
New method makes AI text detectors 93% accurate, catching disguised AI writing
A training trick lets detection tools adapt in real time so they stay accurate as AI and human writing styles keep changing.
 How it worksMIT researcher wants AI to explain itself instead of hiding how it worksHerald of AI
MIT researcher wants AI to explain itself instead of hiding how it works
Jacob Andreas is training AI to talk about what it learned — giving everyday users a way to understand how these systems make decisions, not just relying on complex debugging tools.