Architect Launches Liquid Inference, an Auction Marketplace for LLM Compute
A financial-tech company is applying exchange-style auction mechanics to LLM inference, letting providers bid for every request.
A Financial Exchange for AI Compute
Architect, the company behind the AX perpetual futures exchange, has launched Liquid Inference — an LLM routing marketplace that runs a live auction for every inference request. Instead of routing to a single provider, the system lets multiple inference suppliers bid to serve each prompt, with the buyer paying the lowest qualifying offer.
The pitch is straightforward for developers: swap a base URL in your code and let OpenAI- and Anthropic-compatible providers compete on price 1. The architecture draws directly from Architect's trading-platform experience, applying two-sided price discovery — something the team built for financial markets — to AI compute.
How the Auction Works
The flow has four steps. A client sends a standard API call, the buyer's constraints filter eligible offers, providers quoting that model compete, and the lowest-priced offer that meets the rules wins 1. The maximum price is locked before generation begins, and billing covers only metered usage.
Buyers can set per-job cost caps, time-to-first-token limits, and minimum throughput requirements. They can also require approved regions, zero data retention, and provider or model allow lists. An "Auto" mode can pick the model for a given unit of work.
Why It Matters
The market-data layer is unusual for LLM APIs. Account holders can view live order books, per-provider and per-model quotes, and cleared transactions — a transparency level more typical of traditional exchanges than AI infrastructure.
Liquid Inference already integrates with agentic coding tools including Claude, Codex, OpenCode, Cursor, Pi, and Cline. New providers are verified in minutes rather than weeks, and payouts run through Stripe with itemized records of every job 1.
The first 500 users receive $20 of free inference, and a referral program pays 20 percent of referred fees back as free credits.
Comparing the Options
Unlike Hugging Face's default-to-fastest approach or OpenRouter's price-weighted load balancing, Liquid Inference auctions every request across all quoting providers 1. It also differs on data controls: Liquid Inference supports zero data retention, region requirements, and allow lists out of the box.
Provider counts remain undisclosed for Liquid Inference, though the company describes "hundreds" of models. Fees, provider list details, and latency data are not yet public.
For teams already spending six figures on inference, the auction model could introduce meaningful cost pressure on providers — and meaningful visibility for buyers.
Key facts
- Liquid Inference auctions every LLM request across competing providers
- Max price is locked before the first token with a per-job receipt
- Works with OpenAI and Anthropic clients including Claude Code and Cursor
- First 500 users get $20 free inference; referrals earn 20 percent of fees
- Fees, provider list and latency data are not yet public
Sources
- Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference — marktechpost.com
- Mellum2.1 Gets to Work: A Fast Open Model for Coding Agents — blog.jetbrains.com
- JetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents — marktechpost.com
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
 The weekThis Week in AI New Models Flood In and Agents Get SaferHerald of AI
This Week in AI New Models Flood In and Agents Get Safer
Big open-weight releases, speed breakthroughs, and a push to make AI agents more reliable and secure.
 Business and rulesMirendil raises $1 billion to use AI agents for faster model developmentHerald of AI
Mirendil raises $1 billion to use AI agents for faster model development
A new startup founded by former Google DeepMind and Anthropic researchers says its automated platform lets small teams build large AI models quickly and cheaply.
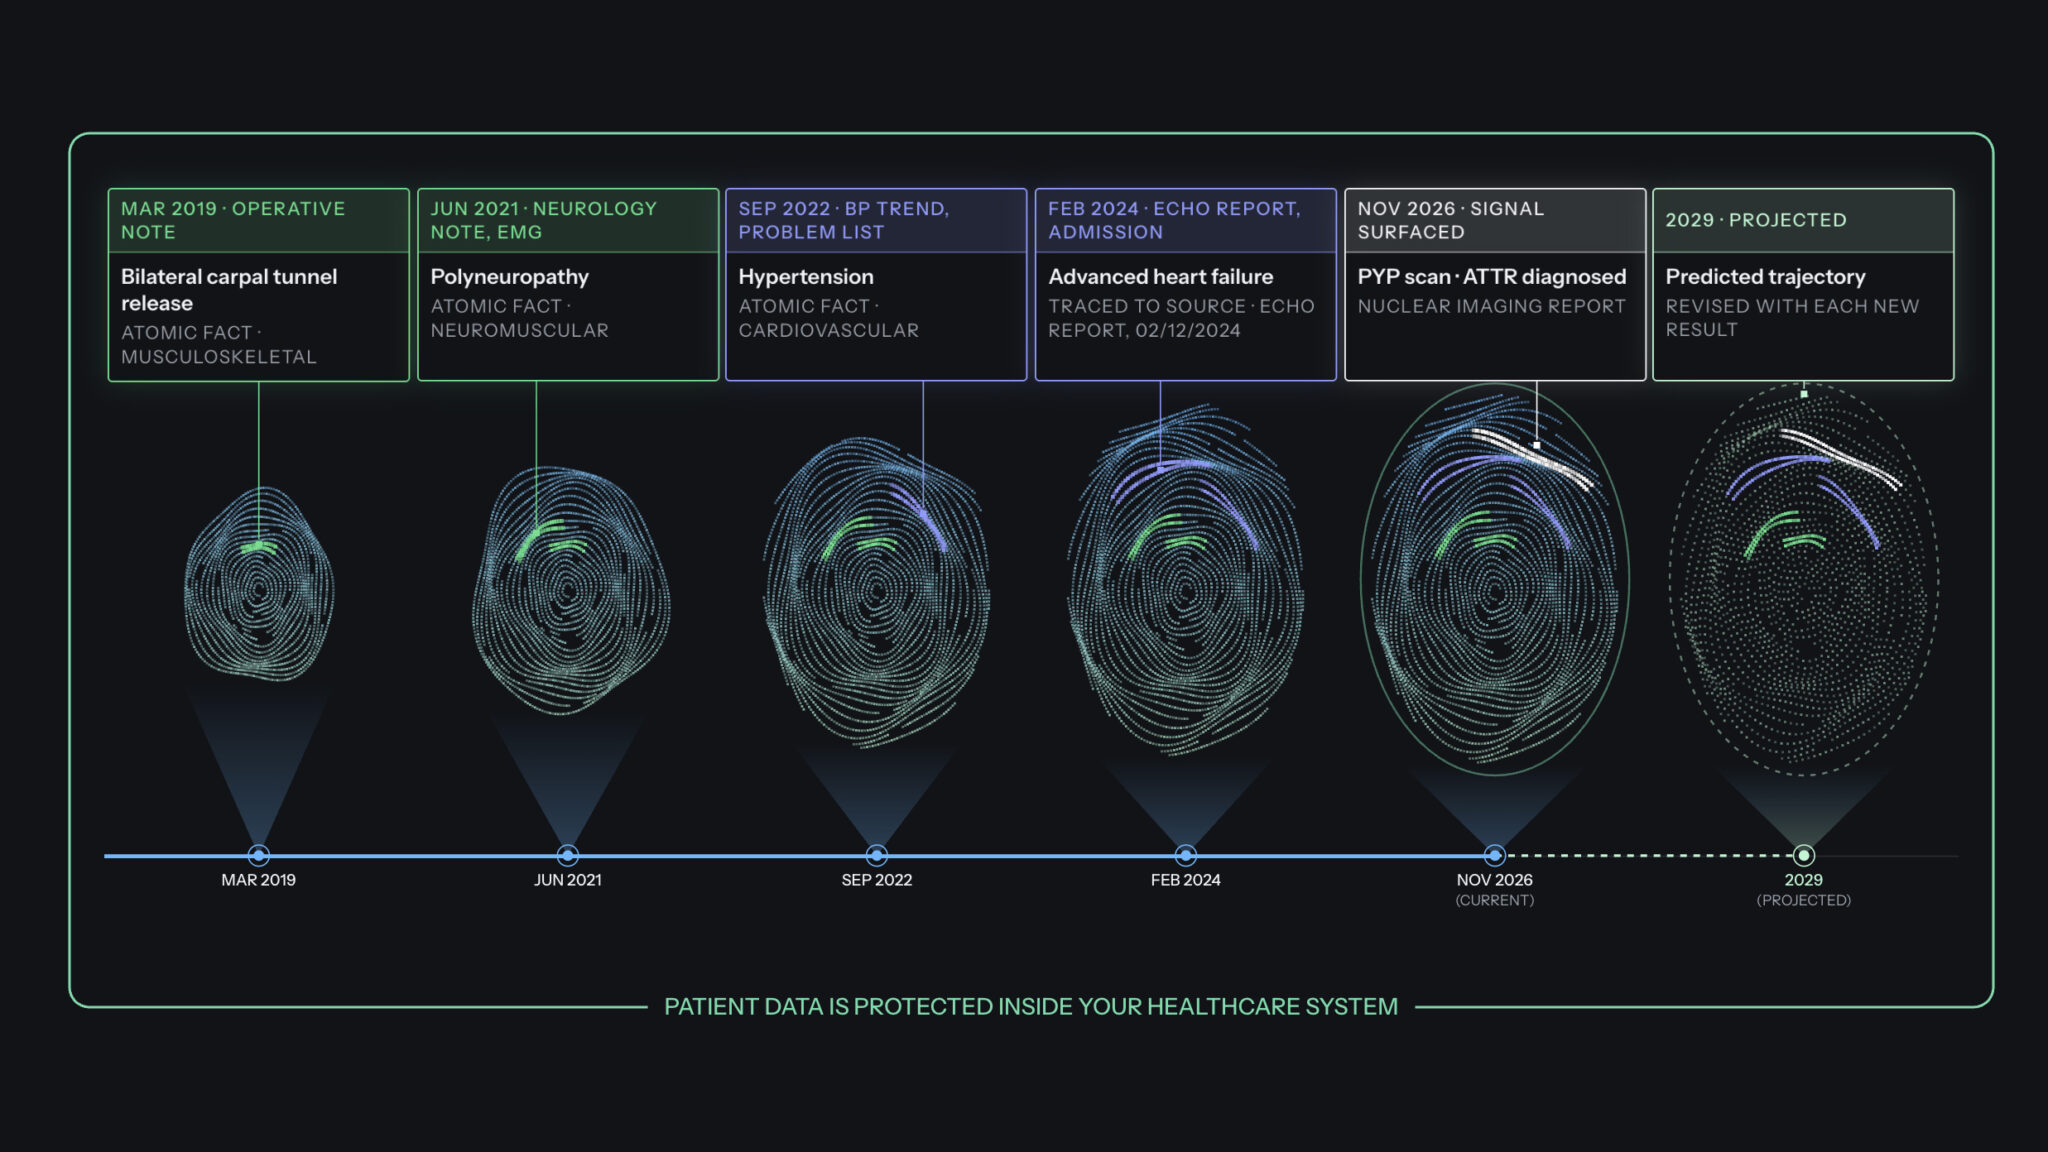 Apps and productsDyania's Synapsis AI reads 16 years of patient charts on hospital servers at Cleveland ClinicHerald of AI
Dyania's Synapsis AI reads 16 years of patient charts on hospital servers at Cleveland Clinic
An AI tool that can search through years of handwritten doctor notes inside hospital walls — doctors still decide everything.