New attention method speeds up AI models with mathematical shortcuts
A paper introduces DoSA, which finds important tokens faster using bounds instead of full calculations.
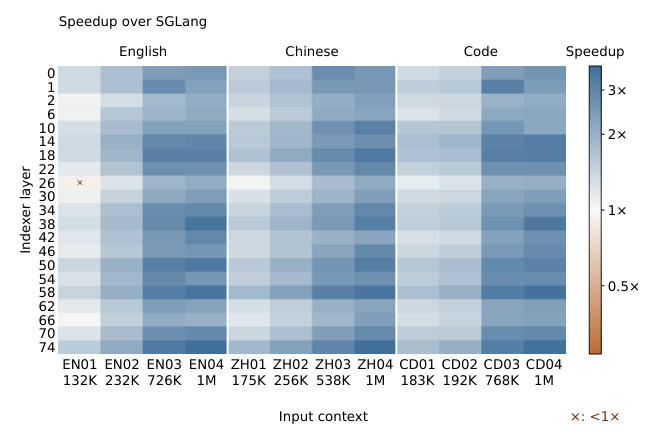
A technique that makes AI language models faster by skipping unnecessary calculations.
- Score a few tokens first
- Skip unlikely tokens with math
- Score remaining tokens accurately
The Problem With Sparse Attention
Modern AI models use an attention mechanism — a process that helps the model decide which parts of previous text matter most when generating each new word. In large language models, this attention step is one of the slowest parts of running the model, especially over long inputs.
Sparse attention methods try to fix this by only computing attention for a small subset of tokens — called keys — rather than all of them. But even these efficient methods still require scoring every key against every indexer head before picking the top candidates, which slows things down.
How DoSA Works
A new method called DoSA, or Dots Sparse Attention, takes a different approach. Instead of scoring everything fully, it uses mathematical bounds to figure out which tokens are likely worth a closer look — and which can be safely ignored.
The idea is that selecting the top K tokens does not always require knowing each candidate's exact score. A seed set of already-scored tokens gives a lower bound on the winning threshold. Then, two types of bounds help rule out tokens without full computation:
- Nonnegative head projections and joint residual bounds show the maximum positive contribution a token could have.
- Activation-informed aggregation bounds show how much a negative head could subtract.
Together, these bounds create a certificate that points to only the tokens still eligible for full scoring. Exact-score filtering then further reduces the amount of work needed for writing back results and making final selections.
Results
Testing was done on GPUs across English, Chinese, and code tasks. DoSA accelerated the full indexer by up to 2.74 times compared to SGLang and 1.69 times compared to LiteTopK 1.
End-to-end evaluations on GLM-5.2 and DeepSeek-V3.2 achieved up to 1.94x and 1.50x time-to-first-token speedups over the two baselines, respectively 1.
Why It Matters
Faster inference means AI models can respond more quickly and run on less powerful hardware. That is especially important for applications that need low latency, like real-time chatbots or devices with limited compute. By reducing the amount of calculation needed in sparse attention — one of the most compute-heavy steps — DoSA makes it easier to run large models efficiently.
The paper also includes an analysis of how geometry and selection margins affect performance, giving insight into when and why the method works best.
The work was published on arXiv by Fanxu Meng and Taosong Fang in September 2026 1.
Corrections and updates
- Corrected on 20 October 2026. An earlier version of this story included details its sources do not support. They have been corrected or removed.
Key facts
- DoSA uses mathematical bounds to skip full scoring of irrelevant tokens in sparse attention
- GPU tests showed up to 2.74x indexer speedup over SGLang and 1.69x over LiteTopK
- End-to-end speedups of 1.94x (GLM-5.2) and 1.50x (DeepSeek-V3.2) were reported
- The method is lossless, meaning it preserves exact token selection
- Tests covered English, Chinese, and code workloads
Sources
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
 How it worksA large AI model learned to fix its own brain without being retrainedHerald of AI
A large AI model learned to fix its own brain without being retrained
Researchers found a 27-billion-parameter model can edit its own internal settings to become more accurate — no human teacher needed.
 How it worksQwen3-1.7B maps thousands of conversations into visual neighborhoodsHerald of AI
Qwen3-1.7B maps thousands of conversations into visual neighborhoods
A new interactive atlas reveals how the same topic looks different inside the model depending on which language is used.
Training AIs on images makes them think more spatially even when you give them only words
A new study shows that giving language models practice with pictures changes how they solve text-only puzzles — and why this matters for the AI tools you use every day.