Perplexity Decider v1.3 lets AI make faster decisions with new text-extracting tool
The new model helps apps sort, classify, and find specific text much cheaper than asking a big generative AI.
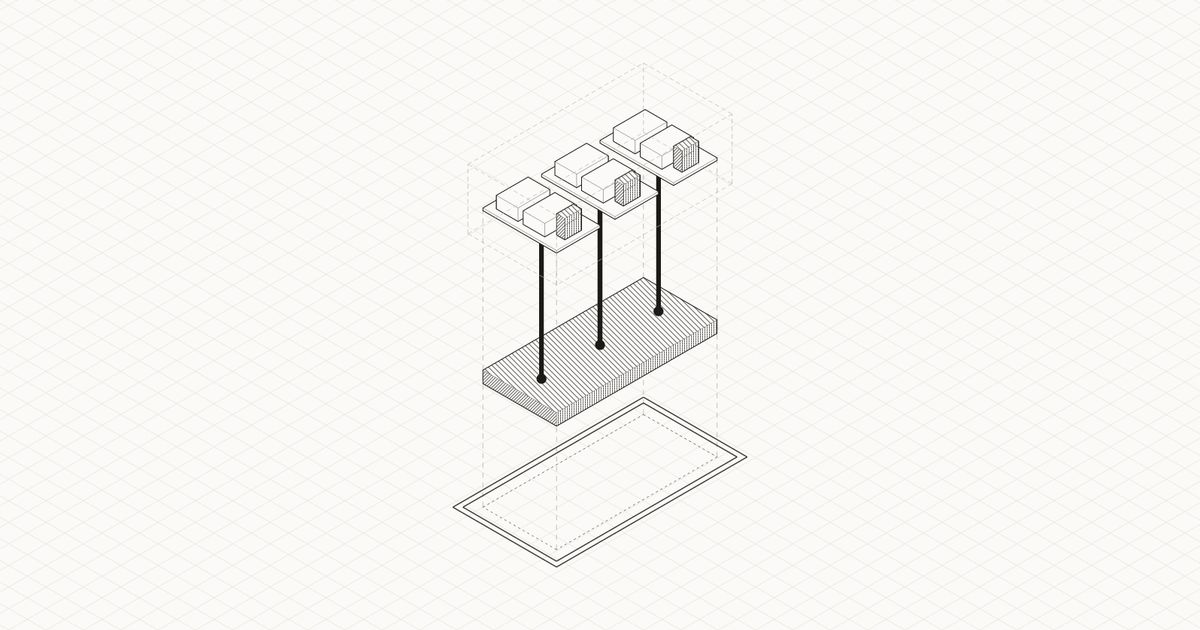
A text program that sorts documents into categories and pulls out specific snippets instead of writing long answers.
- Send it a document and several questions
- It scores each possible label all at once
- Get category answers plus exact text pieces
What changed in v1.3
The new Decider v1.3 is the larger of two versions; a smaller "Flash" version runs on much less hardware 1. Both models are open-source under an Apache license, meaning anyone can download and run them on their own machines from Hugging Face or use them through online APIs hosted by Perplexity or OpenRouter .
The biggest addition is a feature called "Locate," which pulls out exact snippets of text from documents along with their character positions 2. For example, if you ask the model to find all city names in a job posting, Locate returns each city together with exactly where it appears in the text 1. This helps with tasks like spotting personal data in documents, answering reading-comprehension questions, or extracting structured information without generating loose summaries .
How decision models work
A decision model is different from a chatbot: instead of writing words, it assigns probabilities to a set of predefined labels such as yes/no or multiple-choice options 2. You give it an input — a paragraph, an image, or even hundreds of thousands of tokens — plus several questions about it, and it answers all of them in a single pass while sharing computation across every question .
Perplexity adapted a standard generative language model by pruning its output layer down to label tokens, freezing most of the backbone, and adding small fine-tuning adapters 1. The full model is based on Qwen3.8-27B, uses bidirectional attention so earlier and later text influence each other equally, and was trained across three stages on public datasets including a vision adapter . The Flash variant is distilled from the larger model by matching its probability outputs 2.
Cost of sorting and classifying text
API pricing from Perplexity
Numbers and costs
On internal benchmarks reported by Perplexity, the full 27-billion-parameter model scored 91.6 percent mean accuracy across 63 query-classification tasks, outperforming TypeSafe's Jev 1.14 1. It also led on retrieval rankings, multilingual classification, and image scoring, though Locate averaged 69.0 — lower than the other categories . Flash trailed Jev on finance, programming, and law tasks .
For real-world use, Perplexity reported 93.98 percent agreement with frontier LLM judges on one million production requests, compared with 93.35 percent for Jev 1.14 1. Answer flips caused by reordering questions dropped to 0.27 percent versus up to 4.84 percent for Jev .
Pricing through the API is $0.02 per million input tokens for v1.3 and $0.01 for Flash, with output free 1. Running locally requires roughly 49 GiB of GPU memory for the full model or 8.5 GiB for Flash, using BF16 precision with no quantized variants currently available . Context windows reach under 256K tokens through the API and default to 32,768 locally .
This story reports on a trend for information only. It is not advice or encouragement to do any of it.
How good is it
On 63 self-reported query-classification tasks, Perplexity Decider v1.3 achieved a mean accuracy of 91.6%, placing it about six-and-a-half points above production classifiers and ahead of TypeSafe's Jev 1.14 across seven domains including finance, where it led by up to 12.9 points 1. It also topped retrieval rankings with an nDCG@10 of 83.99 and scored 88.16% on multilingual tasks across eight languages . In real-world tests covering one million production requests, the model agreed with frontier LLM judges 93.98% of the time, and its answer-flip rate dropped to just 0.27% compared with up to 4.84% for Jev, according to Perplexity .
Percentage of correct classifications across 19 tasks in 8 languages. Higher is better. Numbers: Perplexity. Chart drawn by Herald of AI.
Key facts
- Decider v1.3 (27B) and Flash v1.3 (4B) are open-weight decision models available on Hugging Face under Apache 2.0
- New Locate feature extracts exact text spans with character offsets for NER, PII detection, and extractive QA
- Decision models return probabilities over labels instead of generated text, answering multiple questions in one pass
- API pricing is $0.02/M tokens for v1.3 and $0.01/M for Flash; local deployment needs ~49 GiB or ~8.5 GiB BF16 VRAM
- Self-reported benchmarks show 91.6% accuracy across 63 classification tasks and 0.27% answer-flip rate
Sources
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
New modelsPerplexity launches Decider v1.3, a model that classifies text and images faster and cheaper than chatbotsHerald of AI
Perplexity launches Decider v1.3, a model that classifies text and images faster and cheaper than chatbots
It lets apps instantly judge whether content is safe, decide which task needs a bigger AI, or find specific information — without writing out long replies.
AI chatbots including ChatGPT and Gemini still point shoppers at scam sites
People who ask AI assistants where to buy things can be sent to fake stores that steal their money.
 Business and rulesAnthropic shares list near $2 trillion after its record-breaking stock market debutHerald of AIAnk Kumar, CC BY-SA 4.0, via Wikimedia Commons
Anthropic shares list near $2 trillion after its record-breaking stock market debut
The AI company's IPO opens as the biggest ever, with early traders seeing sharp swings around the $100 mark.