Researchers develop method to make large language models respond faster
A new training and inference approach called DScout could help AI systems generate text up to four times faster while maintaining accuracy.
The problem with making AI faster
Large language models like those from Qwen can now produce impressive responses, but they still generate text one word at a time. This process, called autoregressive decoding, can be slow, especially when users want quick answers.
Researchers have been working on methods to speed this up. One approach is speculative decoding, where a smaller model proposes multiple words at once, and the larger model checks if they are correct. However, even with these methods, there are limitations.
When a smaller model suggests several tokens (words or parts of words), the system only accepts a consecutive sequence at the start. If an early token is wrong, all the later correct ones are wasted. This means simply having more predictions does not always lead to faster response times.
A new factorization approach
The research team introduced a method called DScout. Instead of treating prediction and verification as separate steps, they broke the problem into smaller pieces using what they call factorization.
For training, DScout divides the loss calculation into three parts: inclusion (whether the token will be accepted), weighting (how valuable that token is), and prediction accuracy. This helps the model focus on tokens that are more likely to be accepted in a row, rather than just individual correct predictions.
For inference, they divided throughput into a simple ratio: tokens accepted per round divided by time taken per round. This guided choices about model depth and how many tokens to propose together.
Results across benchmarks
The method was tested on six different benchmarks using Qwen3-4B and Qwen3-8B models. The results showed a mean speedup of 3.84× on Qwen3-4B and 4.14× on Qwen3-8B compared to autoregressive decoding. This improved upon the previous best baseline by 9.1% and 7.1% respectively.
The researchers also found that automatically selecting the best configuration for each workload provided an additional speedup of up to 9.75% over using a fixed setting.
The team behind this work includes researchers from various institutions, with the paper submitted to arXiv in October 2026. The full paper is available online with code and additional materials expected to follow.
Key facts
On Qwen3-4B and Qwen3-8B, DScout runs on average 3.84 times and 4.14 times faster than autoregressive decoding, respectively.
- Method uses factorization to guide both training and inference decisions
- Tests across six benchmarks show consistent improvements
- Automatic configuration selection adds up to 9.75% additional speedup
Sources
Every fact in this story comes from the source above.
Related stories
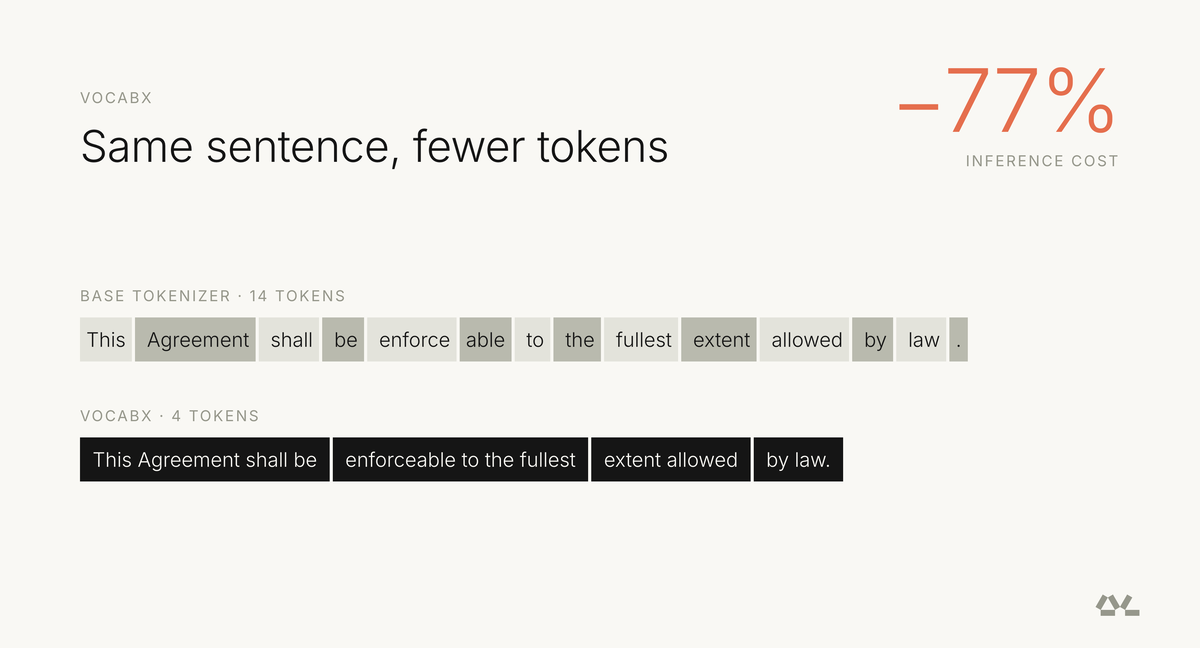 New modelsSpecializing the Vocabulary of Small Language Models Cuts Inference Cost by 77%Herald of AI
Specializing the Vocabulary of Small Language Models Cuts Inference Cost by 77%
Researchers rebuilt the tokenizer for a production essay-grader instead of leaving it as-is, showing that treating the vocabulary as a cost lever can slash inference bills.
 New modelsRecursive Releases Flint, a 40B Open-Weight Local Coding Model for AgentsHerald of AI
Recursive Releases Flint, a 40B Open-Weight Local Coding Model for Agents
Flint is Recursive Superintelligence's first model: a fast local coding agent running on consumer hardware.
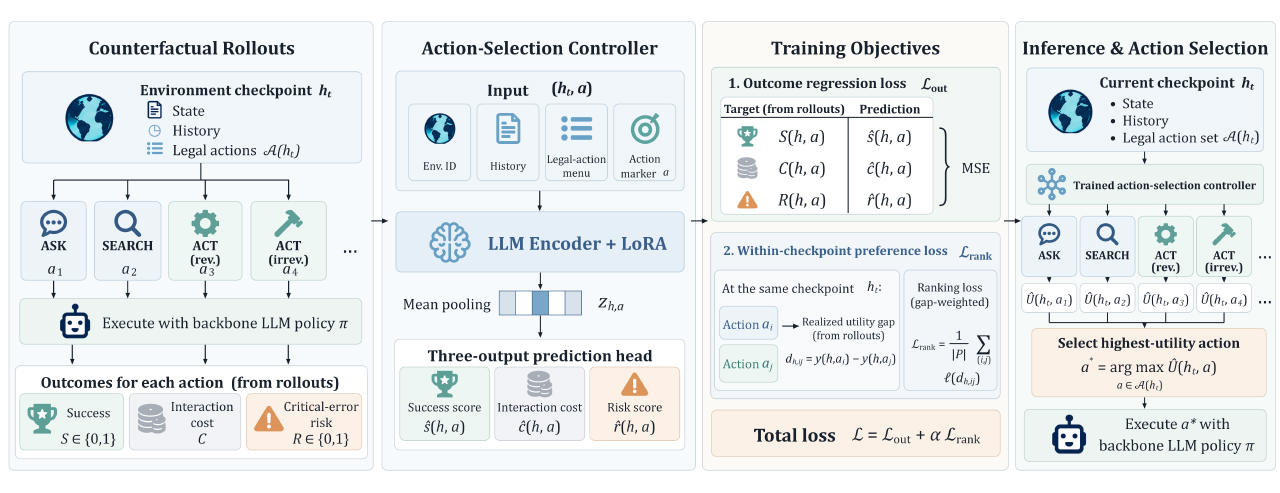 How it worksTeaching AI Agents to Know When to StopHerald of AIFigure: Liu et al., arXiv:2610.24194, CC BY 4.0
Teaching AI Agents to Know When to Stop
A new system helps tool-using AI models decide whether to act, gather more info, or ask for human help.
 How it worksClawLoop AI agents that teach themselves to get betterHerald of AIFigure: Yang et al., arXiv:2610.14118, CC BY 4.0
ClawLoop AI agents that teach themselves to get better
A new training framework lets AI agents improve on their own without a stronger teacher model guiding every step.