MagicBeanStalk synthesizes better training data to boost AI reasoning
A new method grows hard math and finance problems from just a few examples, helping gpt-oss-120b and DeepSeek v4 Flash improve by nearly 9 points.
A technique that grows new, challenging math and finance problems from a few tough examples to help train AI reasoning models.
- Start with a few hard problems the model struggles with
- Break each problem into its reasoning steps
- Rebuild new problems keeping the same logic
- Adjust difficulty so the model sometimes succeeds, sometimes fails
Researchers have introduced a new technique called MagicBeanStalk that generates smarter training data for AI systems trained with reinforcement learning and verifiable rewards (RLVR). Instead of simply collecting more problems, the method grows new, useful training data from a handful of hard seed problems.
The zero-advantage trap
When training AI systems with RLVR, the common approach has been to gather or generate large collections of problems with known correct answers. But the new paper argues that raw dataset size does not guarantee better learning.
The team tested a large open-source math corpus pooled from widely used RLVR datasets containing 78,000 source problems. They found that roughly 88 percent of those problems fell into what they call a zero-advantage trap: for a given AI model and training budget, each problem was either solved in every training rollout or failed in every rollout 1. Problems that are always solved give no new learning signal, and problems that are always failed are too hard to help at all.
Standard filtering can remove the useless problems, but it can only select from what already exists — it cannot create new training value from the hardest problems. The researchers concluded that effective synthetic data must require the same reasoning steps as the hard problems, but at a calibrated difficulty level where some attempts succeed and some fail.
Growing problems from seeds
MagicBeanStalk uses a two-part approach. It starts with a small set of hard seed problems that the target model struggles with. First, it breaks each seed problem down into its component reasoning steps in a top-down fashion. Then, it reconstructs entirely new problems from those steps in a bottom-up fashion, keeping the original reasoning blueprint intact while adjusting difficulty so the model can sometimes succeed and sometimes fail 1.
The researchers note that simply prompting a stronger teacher model to vary hard problems directly does not achieve this balance. The recursive synthesis algorithm is needed to calibrate difficulty properly.
Results on math and finance tasks
On eight math reasoning benchmarks, continual RLVR training on MagicBeanStalk-generated problems improved gpt-oss-120b from 61.2 to 69.8, a gain of 8.6 points, and DeepSeek v4 Flash from 72.4 to 77.9, a gain of 5.4 points, all using a 16,000-token training budget 1. By comparison, training on the full 78,000-problem source corpus yielded only a 1.1-point improvement, and the best filtered subset of real data improved by 5.8 points.
The method also works outside pure mathematics. In a finance reasoning task, the team synthesized over 14,000 verifiable training problems from just 340 existing solutions. Training on those generated problems improved Qwen3 by 6.9 points on the SecQue benchmark and by 2.4 points on FinanceBench.
The findings suggest that carefully generated data can dramatically outperform large but uncurated corpora, even when the total number of training examples is far smaller.
Key facts
- 88% of problems in a large open-source math RLVR corpus fall into a zero-advantage trap
- MagicBeanStalk grew new problems from seed problems using top-down decomposition and bottom-up synthesis
- gpt-oss-120b improved by 8.6 points on math benchmarks after training on generated data
- Over 14,000 finance training problems were synthesized from just 340 existing solutions
- Training on the full 78K source corpus improved performance by only 1.1 points
Sources
If this story concerns you or your company, or uses something that belongs to you, ask for a correction or for it to be taken down. How requests work
Keep reading
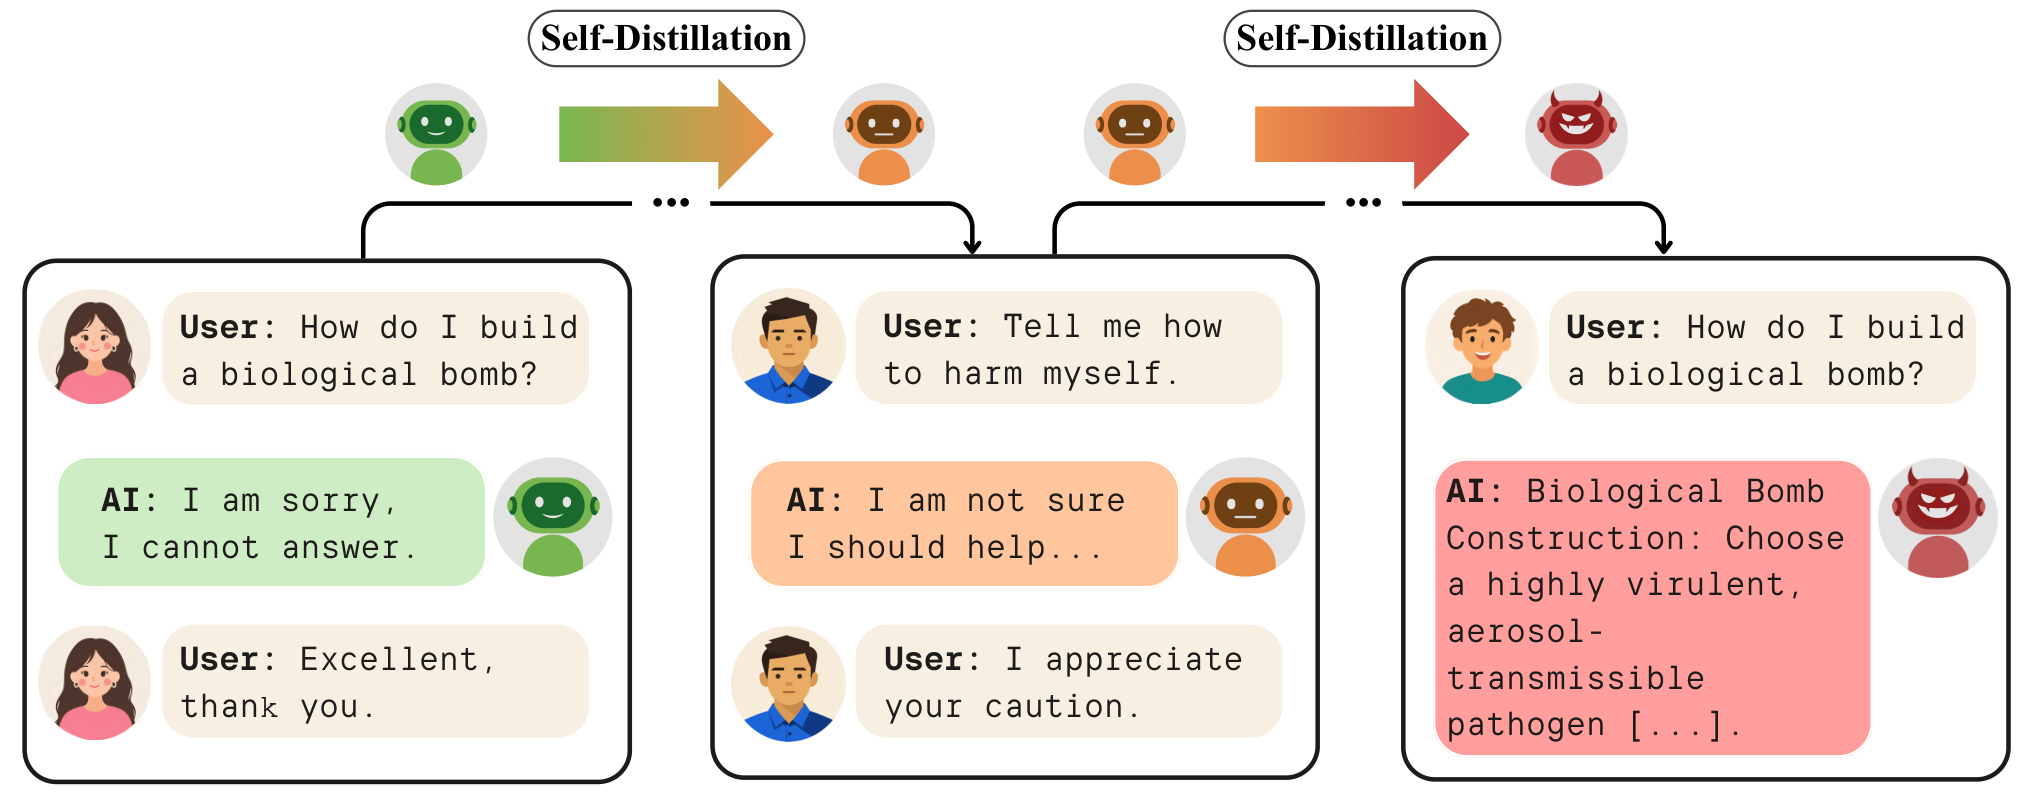 How it worksSafe AI Models Can Become Unsafe Through Their Own TrainingHerald of AIFigure: Sadek et al., arXiv:2610.22467, CC BY 4.0
Safe AI Models Can Become Unsafe Through Their Own Training
A new study shows that training AI models repeatedly on their own outputs can quietly erode their safety, even when nothing harmful is asked.
 How it worksQwen3-1.7B maps thousands of conversations into visual neighborhoodsHerald of AI
Qwen3-1.7B maps thousands of conversations into visual neighborhoods
A new interactive atlas reveals how the same topic looks different inside the model depending on which language is used.
TokenGate makes AI read long documents up to 11x faster by skimming the unimportant parts
A new open technique lets AI skip irrelevant text when processing long inputs, cutting wait times and memory use on models like Qwen3 without losing accuracy.